
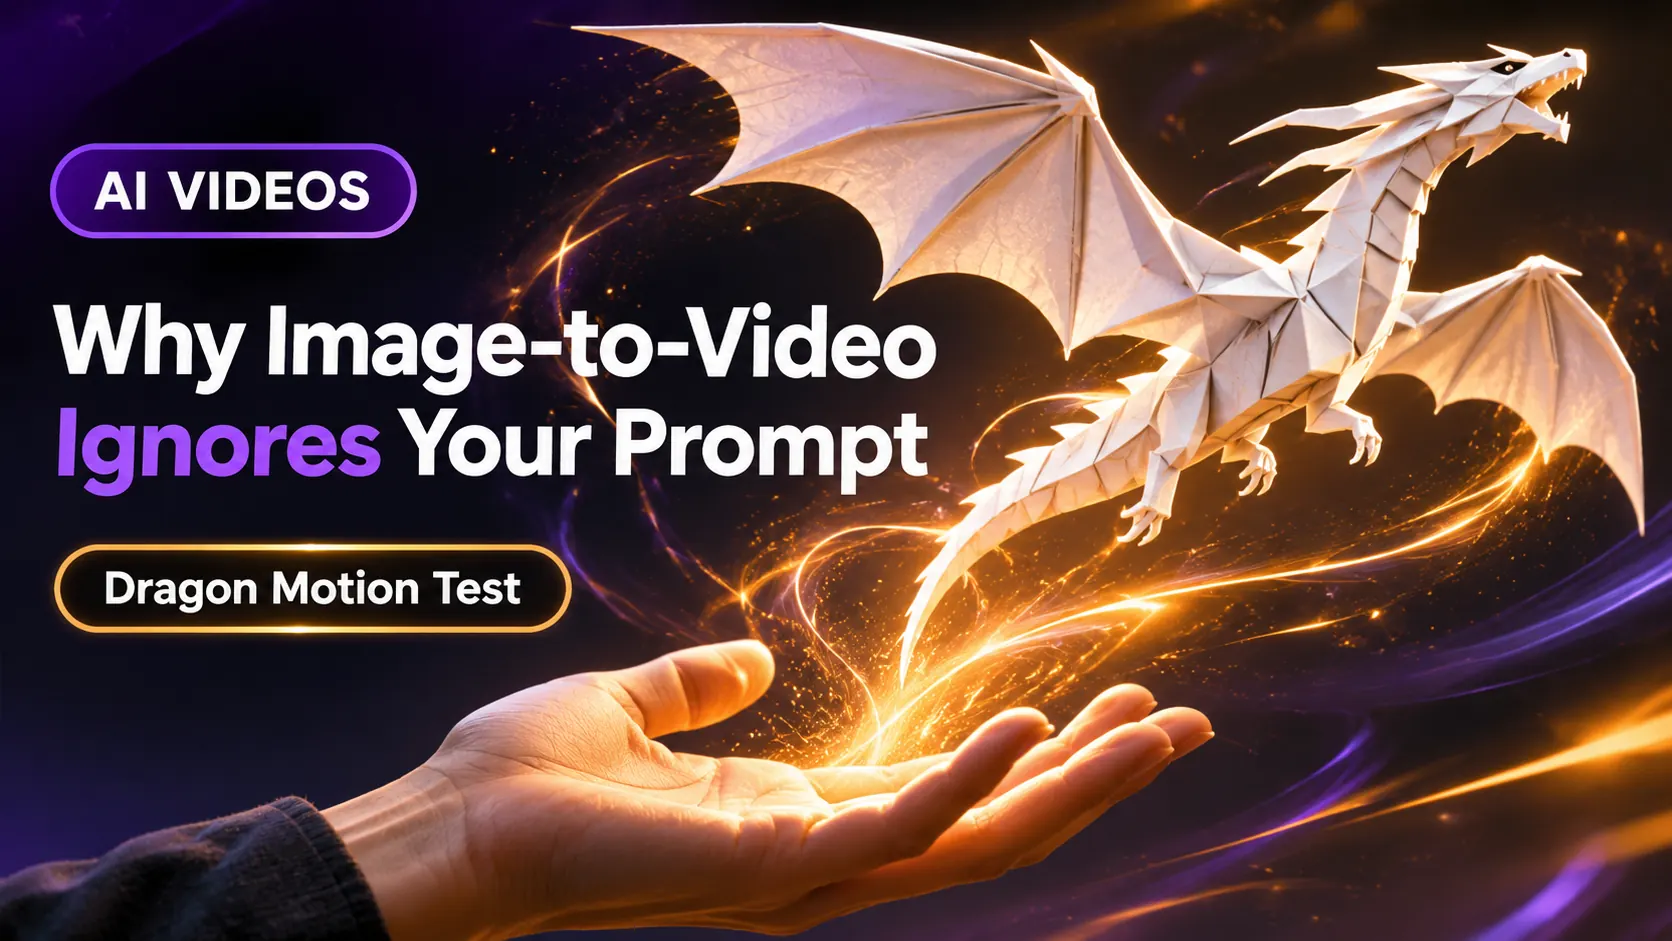
You upload a promising image, ask an AI video generator to make the subject move—and get a clip where almost nothing happens. The wings twitch, the camera drifts, or the background comes alive, but the character never performs the action you asked for. We encountered exactly this problem while trying to make a tiny origami dragon take off from a person’s hand.
Why Does AI Image-to-Video Ignore the Motion Prompt?
In image-to-video generation, the uploaded picture already defines the subject, composition and much of the visual style. The prompt mainly guides what changes over time. Runway’s official prompting guides recommend clear descriptions of subject action, camera movement, direction and timing—not lengthy repetitions of what the image already shows.
Several different failures can look like “the AI ignored me.” The subject might make a small gesture instead of a larger one. The camera may move in place of the character. The animation may begin but never reach the requested ending. Or the model may preserve an attractive source image at the expense of a major change in pose or location. The particular cause cannot be diagnosed from a finished clip alone, but these symptoms suggest different fixes.
- What must move? Name the character or object, not just “the scene.”
- Where must it go? Describe a visible change in position, pose or distance.
- What should the camera do? A locked camera is often easier to evaluate than an unspecified camera move.
Our Real Test: The Origami Dragon That Wouldn’t Fly
We started with an image of a small white origami dragon resting on an open palm. The goal was simple to describe but visually demanding: the dragon should unfold its wings, lift its body and fly away, leaving the hand below.
Attempts 1 and 2: Gen-4 Turbo moved only the wings
We ran two separate five-second generations in Runway Gen-4 Turbo. Each cost 25 credits. In both results, the dragon mainly lifted or moved its wings; it did not convincingly leave the hand. The motion was visible, but it was not the requested takeoff.
Evidence note: These are recorded observations from our own experiment. We are not reproducing the exact original prompts because a verified verbatim copy was not retained for this article. We also have not published the two failed clips here, so readers can evaluate the successful result below, but not independently compare all three outputs.
Attempt 3: First and last frames with MiniMax H3
Instead of paying for another near-identical single-image attempt, we supplied two images: the dragon sitting on the hand as the first frame, and a newly prepared image showing it flying above an empty palm as the last frame. We then used MiniMax H3 through Runway, at 768p for five seconds. Our recorded charge was 52 credits.
The final result more closely matched our goal: the dragon lifted off instead of merely flapping. This does not prove that MiniMax H3 is universally better than Gen-4 Turbo. We changed both the model and the input method, so our test cannot isolate which change mattered most.
| Attempt | Setup | Observed result | Recorded cost |
|---|---|---|---|
| 1 — Origami dragon | Gen-4 Turbo; one image; 5 seconds | Wings moved, but no convincing takeoff | 25 credits |
| 2 — Origami dragon | Gen-4 Turbo; one image; 5 seconds | Similar limited wing movement | 25 credits |
| 3 — Origami dragon | MiniMax H3; first and last frames; 5 seconds, 768p | Dragon lifted into flight | 52 credits |
Total recorded generation cost: 102 credits. Costs reflect our sessions, not a guarantee of current pricing. See Runway’s current model details before generating.
Seven Ways to Fix an AI Image-to-Video Clip With Too Little Motion
1. Start with one physical action
“Make it cinematic and magical” is a visual direction, not a precise motion instruction. Describe what the subject’s body does: stands up, turns, takes two steps, jumps, or rises into the air. Add atmosphere after that action works.
2. State the subject, movement and destination
A usable prompt identifies who moves, how, and where. Instead of “the dragon flies,” specify that the dragon pushes off from the palm and rises above it. This tells the model what a successful shot would visibly contain.
3. Keep the camera still for your first diagnosis
If the prompt also calls for a cinematic orbit, rapid zoom and dramatic reframing, it can become difficult to tell whether the model prioritized camera motion over subject motion. First request a locked, medium-wide camera. After you obtain the desired action, try a moving-camera version.
4. Check the starting image for conflicting cues
The reference image can imply a particular pose, direction or kind of movement. Runway’s official image-to-video guide notes that motion cues in a source image can conflict with your prompt. If the character is cramped in frame or lacks room to move, try a wider starting composition or an image with a more suitable pose.
5. Ask for a plausible sequence, not five actions at once
In a short generation, one clear action may work better than an elaborate chain of turning, running, jumping, flying and landing. If the full story needs multiple actions, divide it into separate shots and edit them together afterward.
6. Use an ending frame when the destination matters
If a model supports first-to-last-frame generation, prepare a second image showing where the character must end up. This can be useful for takeoffs, reveals and transitions that are hard to communicate with text alone. Check both frames for consistent subject appearance, framing and lighting, because mismatched keyframes can introduce new artifacts. A last frame guides the goal; it does not guarantee a physically realistic transition.
7. Change the workflow when repeated attempts fail
After a few unsuccessful generations, simply adding more adjectives may not be the most efficient use of credits. Try simplifying the prompt, improving the image, changing duration where available, adding a last frame, or comparing a different model. Record the result and cost each time so you know whether the change helped.
Example Prompts You Can Adapt
The following are illustrative prompts based on the principles above. They are not exact transcripts of our original dragon experiment and have not been separately tested for this article.
Example 1: A character that actually walks
Example 2: A product rising from a table
Example 3: A dragon takeoff with one starting image
Example 4: A dragon shot with first and last frames
Prompt wording is a starting point, not a reliable command language. Different models interpret details differently, and the input frame often matters as much as the text.
A Quick Troubleshooting Checklist
| What went wrong? | What to try next |
|---|---|
| Only eyes, wings or hair move | Describe the entire body’s displacement; show where the subject ends |
| The camera moves but the character stays put | Use a locked-camera prompt and one specific subject action |
| The action begins but never finishes | Simplify the sequence, consider more duration or a last frame |
| The subject deforms during a jump or turn | Try a better source pose, cleaner composition or smaller action |
| Repeated retries barely change the result | Switch the input strategy or model rather than repeating near-identical prompts |
What We Learned
- Specific, observable movement is more useful than broad stylistic instructions when troubleshooting motion.
- A moving camera is not a substitute for a moving subject.
- In our origami-dragon experiment, two single-image attempts did not achieve takeoff, while a first-and-last-frame setup did.
- That observation suggests a practical workflow, not a universal ranking of video models.
- Tracking failed generations and credit costs makes experimentation more useful—and easier to budget.
For a broader walkthrough of Runway’s models, pricing and our other video tests, see our Runway AI video generator overview. If your main difficulty is preserving a recurring character rather than getting it to move, see How to Keep the Same AI Character in Multiple Videos.
Frequently Asked Questions
Why does my AI image-to-video result barely move?
The model may be preserving the composition of the source image, misinterpreting an ambiguous action, or prioritizing easier local motion or camera movement. Try naming one concrete physical action and checking whether the source image gives the subject room to move.
Does a longer prompt create more movement?
Not necessarily. More words can introduce competing instructions. Start with the most important action, then add details one at a time as needed.
Is a first and last frame always better?
No. It helps when the end position is important and the selected model supports that workflow, but mismatched keyframes can also make the in-between motion harder to generate.
Did MiniMax H3 outperform Gen-4 Turbo in your test?
Our H3 result achieved the dragon takeoff, while two Turbo attempts did not. However, H3 used a different input method with two frames, so this was not a controlled comparison of the models alone.
How many credits did the dragon experiment cost?
Our three recorded generations cost 25, 25 and 52 credits, respectively: 102 credits in total. Prices and available settings can change.
Sources and Editorial Notes
- Runway — Image-to-Video Prompting Guide
- Runway — Gen-4 Video Prompting Guide
- Runway — Gen-4 model specs and credit costs
- Runway — MiniMax H3 model and first/last-frame support
- Runway — Image-to-video overview
Testing disclosure: AI Revolution performed the three dragon generations described above and recorded the outcomes and credit charges. The successful clip is embedded from our YouTube channel. The example prompts elsewhere in this article are suggested troubleshooting templates, not additional completed tests. All interpretations are limited to this case; model behaviour and pricing can change.